

 Microsoft
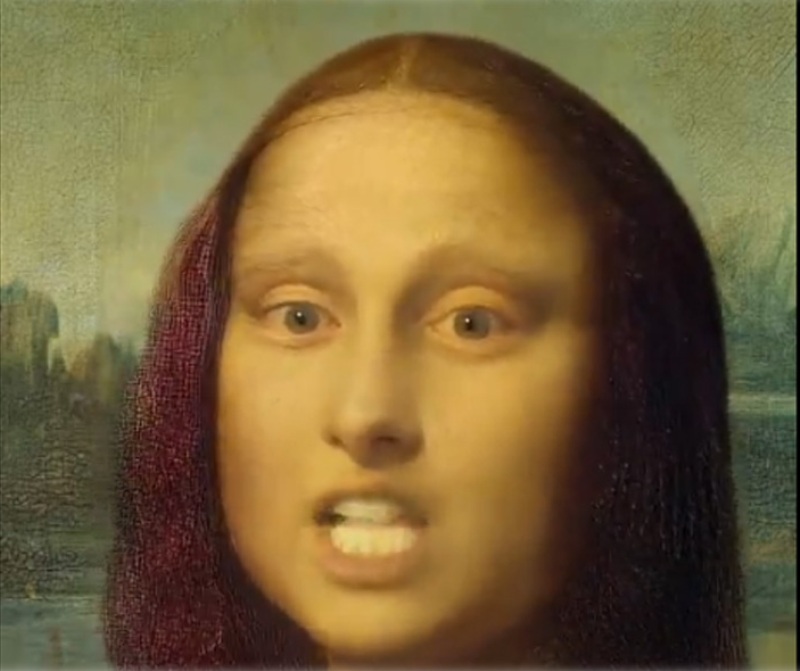
Mona Lisa is rapping in a new viral video, check out how Microsoft made it possible with AI
The iconic Mona Lisa is no longer only smiling, she also prefers to sing and even rap, thanks to the new artificial intelligence technology unveiled by Microsoft.
Last week, Microsoft researchers detailed a new AI model they’ve developed that can take a still image of a face and an audio clip of someone speaking and automatically create a realistic looking video of that person speaking, reported CNN.
Microsoft just dropped VASA-1.
— Min Choi (@minchoi) April 18, 2024
This AI can make single image sing and talk from audio reference expressively. Similar to EMO from Alibaba
10 wild examples:
1. Mona Lisa rapping Paparazzi pic.twitter.com/LSGF3mMVnD
The video can leave people stunned as it is complete with lip-syncing and natural face and head movements.
In one demo video, researchers showed how they animated the Mona Lisa to recite a comedic rap by actor Anne Hathaway, the American news channel reported.
Speaking about outputs from AI model named VASA-1, Micorsoft said: "We introduce VASA, a framework for generating lifelike talking faces of virtual characters with appealing visual affective skills (VAS), given a single static image and a speech audio clip. Our premiere model, VASA-1, is capable of not only producing lip movements that are exquisitely synchronised with the audio, but also capturing a large spectrum of facial nuances and natural head motions that contribute to the perception of authenticity and liveliness."
"The core innovations include a holistic facial dynamics and head movement generation model that works in a face latent space, and the development of such an expressive and disentangled face latent space using videos. Through extensive experiments including evaluation on a set of new metrics, we show that our method significantly outperforms previous methods along various dimensions comprehensively. Our method not only delivers high video quality with realistic facial and head dynamics but also supports the online generation of 512x512 videos at up to 40 FPS with negligible starting latency. It paves the way for real-time engagements with lifelike avatars that emulate human conversational behaviours" the website said.
Support Our Journalism
We cannot do without you.. your contribution supports unbiased journalism
IBNS is not driven by any ism- not wokeism, not racism, not skewed secularism, not hyper right-wing or left liberal ideals, nor by any hardline religious beliefs or hyper nationalism. We want to serve you good old objective news, as they are. We do not judge or preach. We let people decide for themselves. We only try to present factual and well-sourced news.
Support objective journalism for a small contribution.